Decoding AI Jargons with Nikhil

Tokenization :-
Tokenization is the process of turning text into a sequence of tokens, which can be words, subwords, or characters.. LLM can understand hindi, english, hinglish in reality what happen all ai model have there own tokenization mechanism like (gemini,gpt-4o,deepseek)
what tokenization do simply take user input convert into integers.
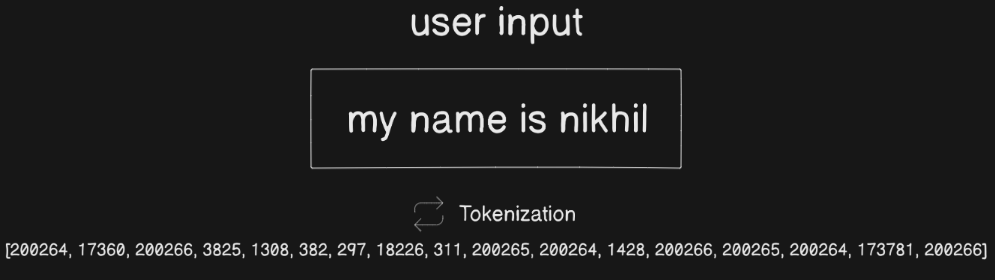
gpt-4o have 200k approx token
import tiktoken

encoder = tiktoken.encoding_for_model("gpt-4o")

print("vocab size",encoder.n_vocab)
If you want to visualize it, you can use this link: https://tiktokenizer.vercel.app
Encoder :-
The process of converting user input into tokens
import tiktoken
encoder = tiktoken.encoding_for_model("gpt-4o")

text = "hello my name is nikhil"
token = encoder.encode(text)
print("Token",token) # [24912, 922, 1308, 382, 297, 18226, 311]
Decoder :-
The process of converting tokens back into text
import tiktoken
encoder = tiktoken.encoding_for_model("gpt-4o")

my_token = [24912, 922, 1308, 382, 297, 18226, 311]

decoded = encoder.decode(my_token)
print("Decoded token",decoded) # hello my name is nikhil
Vector Embeddings
Before we start, let's understand what vector embedding is. Stay with me.
if i say uncle => aunt
mother => father
boyfriend=> what ??
Your answer might be "girlfriend" because your brain makes connections or relations.
What vector embedding does is take these words and bring out their semantic meaning.
let take example of IPL teams
| MI | CSK | RCB | |
| Trophy | 5 | 5 | 0 |
When you search for which teams have won 5 IPL trophies, it shows MI and CSK.
pip install sentence-transformers
from sentence_transformers import SentenceTransformer

model = SentenceTransformer('all-MiniLM-L6-v2')
sentences = ['You are reading nikhil blog.']

embeddings = model.encode(sentences)
print(embeddings)
If you want to visualize, you can use this link: https://projector.tensorflow.org/
Positional Encoding :-
Let's take two sentences: the first one is The River bank and the second one is The SBI bank. Both have different meanings, but their semantic meanings are not the same.
Both end with the word "bank", but their meanings are totally different. Why? Because the context and position of the word "bank" change its meaning.
positional encoding assigns numerical patterns to each position in the sequence, which helps differentiate between phrases like "river bank" and "SBI bank" even though the word "bank" is the same, its meaning depends on where it appears.
The motive of positional encoding is basically to tell the model the position of each token .
Self Attention :-
In self-attention, we allow tokens to interact with each other and update the meaning of each token based on the surrounding words
In this case, the words in "The river bank" interact with each other. The word "river" will indicate that it is not the kind of bank that stores money. When tokens communicate with each other, they update their semantic meaning in the sentence.
Temperature :-
Temperature is a parameter that controls the randomness or creativity of the model’s output when it's generating text.
lower temperature :- the model become more confident for example you ask how are you? the answer might be fine when do low the temperature.
higher temperature :- the model become more creative for example take same question how are you? the answer be I'm vibin’ in the cloud, dancing through electric thoughts and caffeinated code, dreaming in binary while riding data waves like a digital surfer.
Softmax :-
The softmax function creates a probability distribution for each output token in the vocabulary, allowing us to generate output tokens with certain probabilities.
For example:
"NDA" has a probability of 90
"INDIA" has a probability of 10
Softmax will choose "NDA" because it has a higher probability.
Knowledge Cutoff :-
If your model is trained in 2024 and you ask a question related to 2025, it might not have the answers to those questions.